Research paper / RESOURCE PROFILE

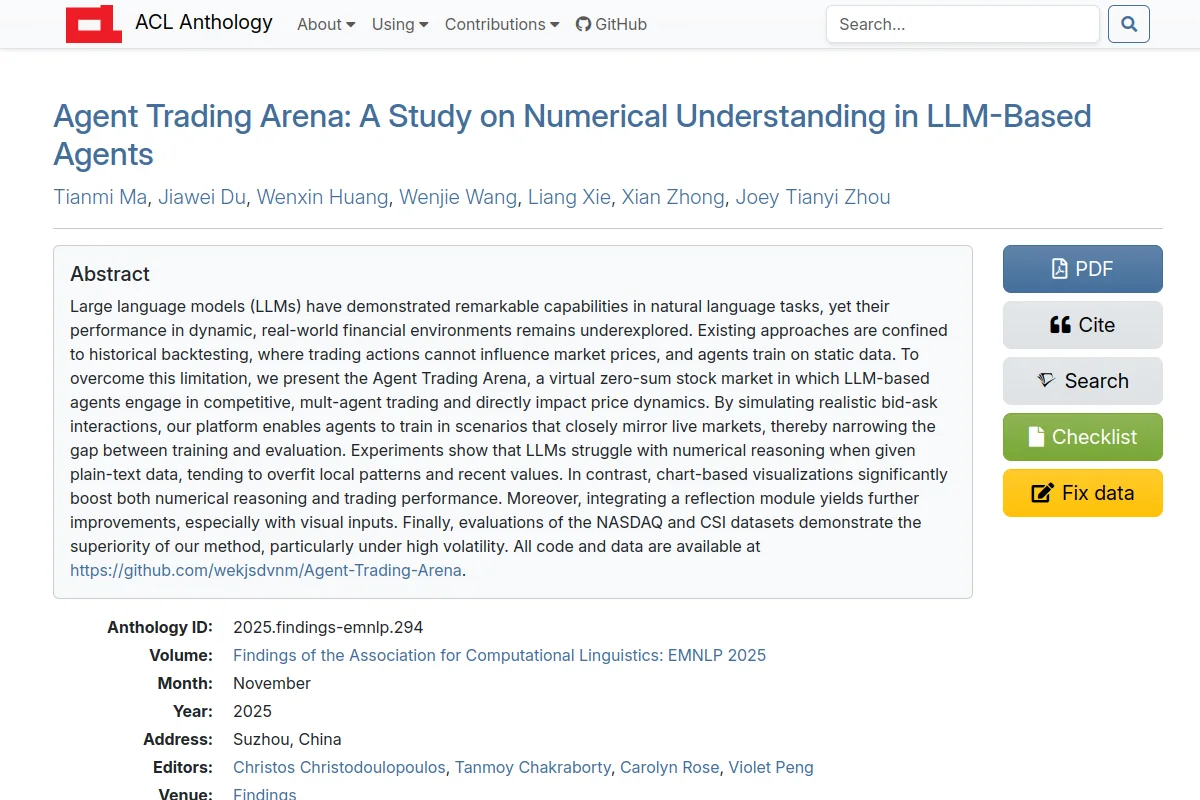
FinRL-Podracer: High Performance and Scalable Deep Reinforcement Learn

High performance and scalable deep reinforcement learning for quantitative finance. ACM International Conference on AI in Finance, ICAIF 2021

arxiv.orgPublished Nov 7, 2021
Visit source website ↗
Screenshot unavailableResource information and source links remain available. FinRL-Podracer: High Performance and Scalable Deep Reinforcement Learn — reviewed source website screenshot
Reviewed source screenshot · recorded Oct 11, 2026 View source ↗

Overview

High performance and scalable deep reinforcement learning for quantitative finance. ACM International Conference on AI in Finance, ICAIF 2021

Topics & capabilities

reinforcement-learningstrategiespapereducation

Publication information

Publication title
FinRL-Podracer: High Performance and Scalable Deep Reinforcement Learning for Quantitative Finance
Authors
Zechu Li, Xiao-Yang Liu, Jiahao Zheng, Zhaoran Wang, Anwar Walid, Jian Guo
Published
Nov 7, 2021
Last publication revision
Nov 7, 2021
Venue / journal
ACM International Conference on AI in Finance, 2021
Subject areas
q-fin.CP, cs.CE
DOI
10.1145/3490354.3494413 ↗
Publication source
arxiv.org · abs/2111.05188v1 ↗

Source: arXiv API · observed Oct 11, 2026.

Source links & provenance

https://arxiv.org/abs/2111.05188 ↗

Discovery references

References explain how this resource entered the collection. They do not represent an endorsement.

Explore related resources

Sign In

Register

Reset Password

Please enter your username or email address, you will receive a link to create a new password via email.