1709-WRPN-Intel-ICLR2018
arxiv.orgPublication: WRPN: Wide Reduced-Precision Networks. Published Sep 4, 2017.
- Published
- Sep 4, 2017
- Authors
- 4
DUCKQUANT / THE QUANT & AI DIRECTORY
14,444 resources, ranked by in-directory PageRank
Showing 2,269–2,304 of 14,444 resources
Publication: WRPN: Wide Reduced-Precision Networks. Published Sep 4, 2017.
Publication: Ternary Weight Networks. Published May 16, 2016.
Publication: XNOR-Net: ImageNet Classification Using Binary Convolutional Neural Networks. Published Mar 16, 2016.
Publication: Data-Free Quantization Through Weight Equalization and Bias Correction. Published Jun 11, 2019.
Publication: Training and Inference with Integers in Deep Neural Networks. Published Feb 13, 2018.
Publication: Training Quantized Neural Networks with a Full-precision Auxiliary Module. Published Mar 27, 2019.
Publication: Learning to Quantize Deep Networks by Optimizing Quantization Intervals with Task Loss. Published Aug 17, 2018.
Publication: Training Deep Neural Networks with 8-bit Floating Point Numbers. Published Dec 19, 2018.
Publication: Scalable Methods for 8-bit Training of Neural Networks. Published May 25, 2018.
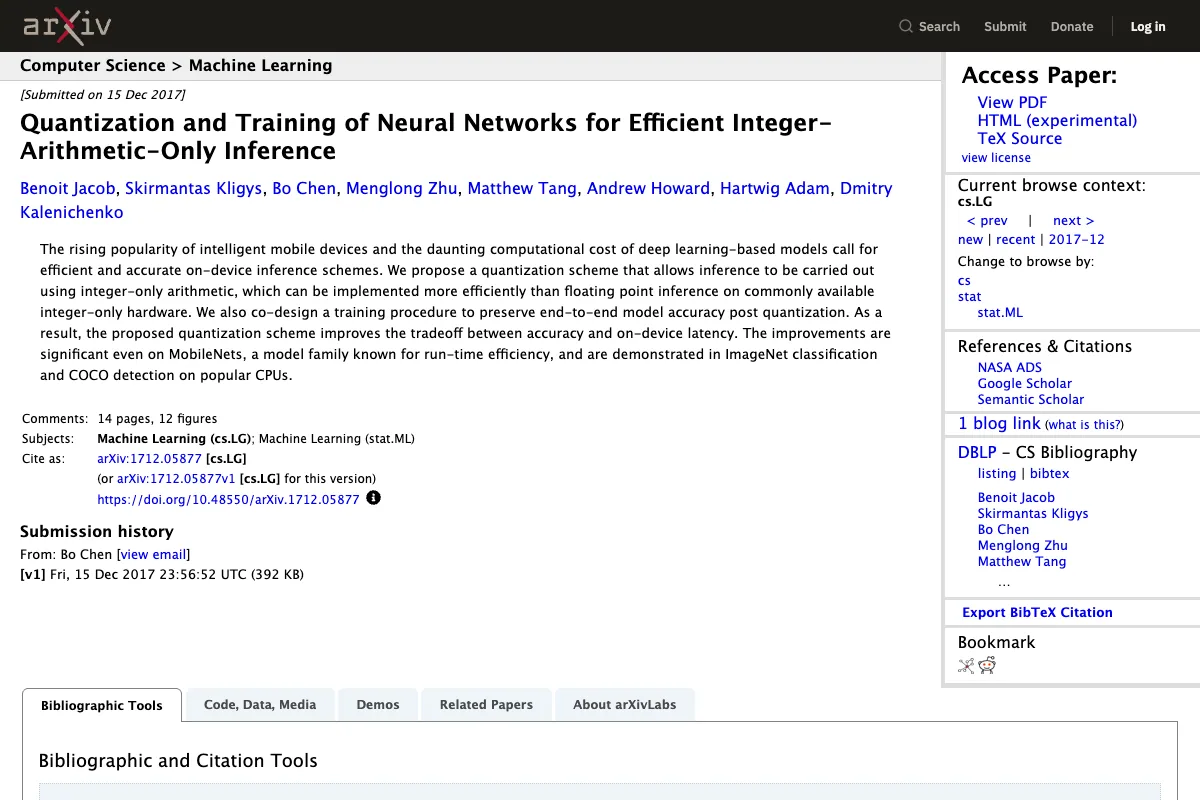
Publication: Quantization and Training of Neural Networks for Efficient Integer-Arithmetic-Only Inference. Published Dec 15, 2017.
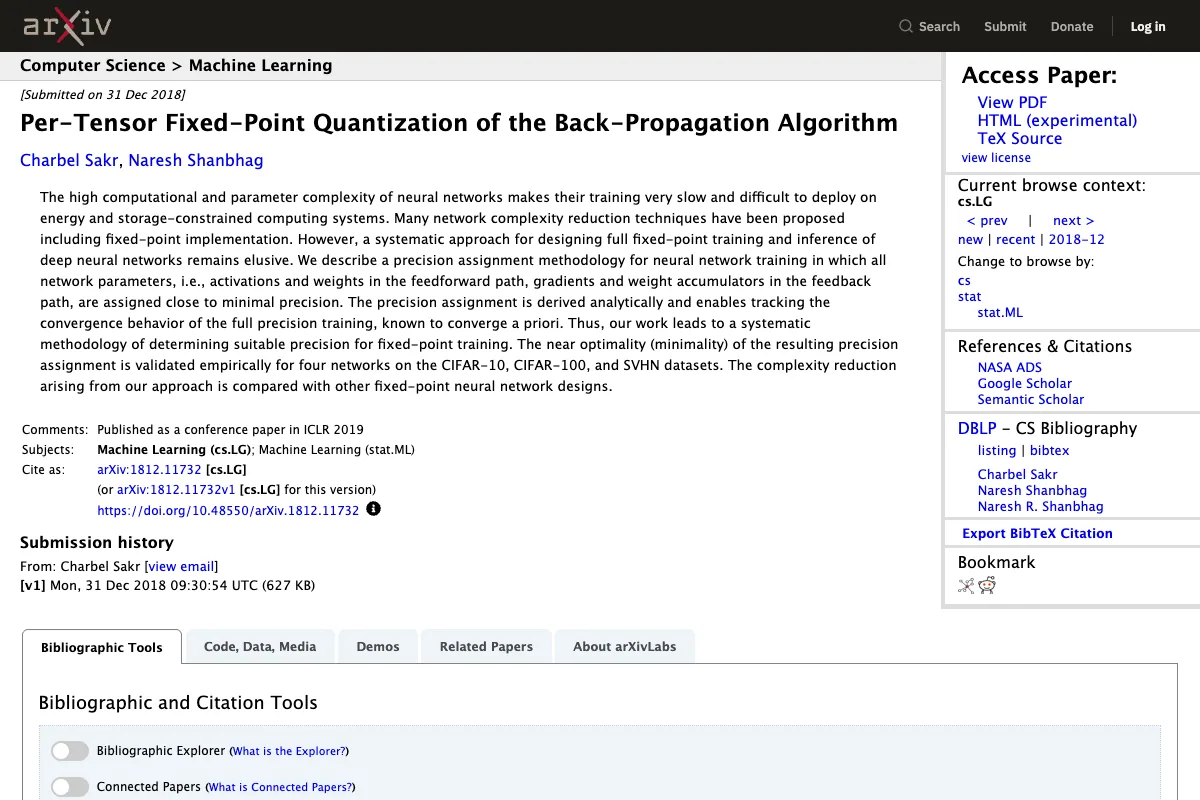
Publication: Per-Tensor Fixed-Point Quantization of the Back-Propagation Algorithm. Published Dec 31, 2018.
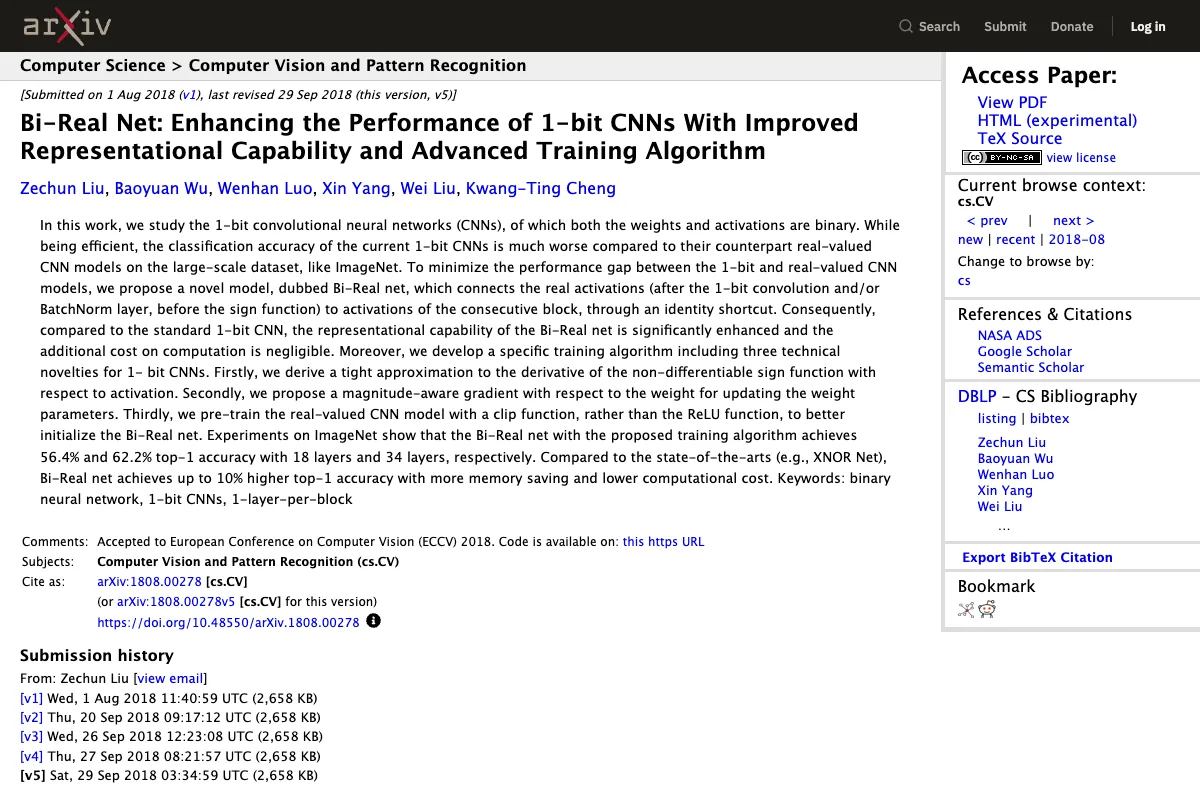
Publication: Bi-Real Net: Enhancing the Performance of 1-bit CNNs With Improved Representational Capability and Advanced Training Algorithm. Published Aug 1, 2018.
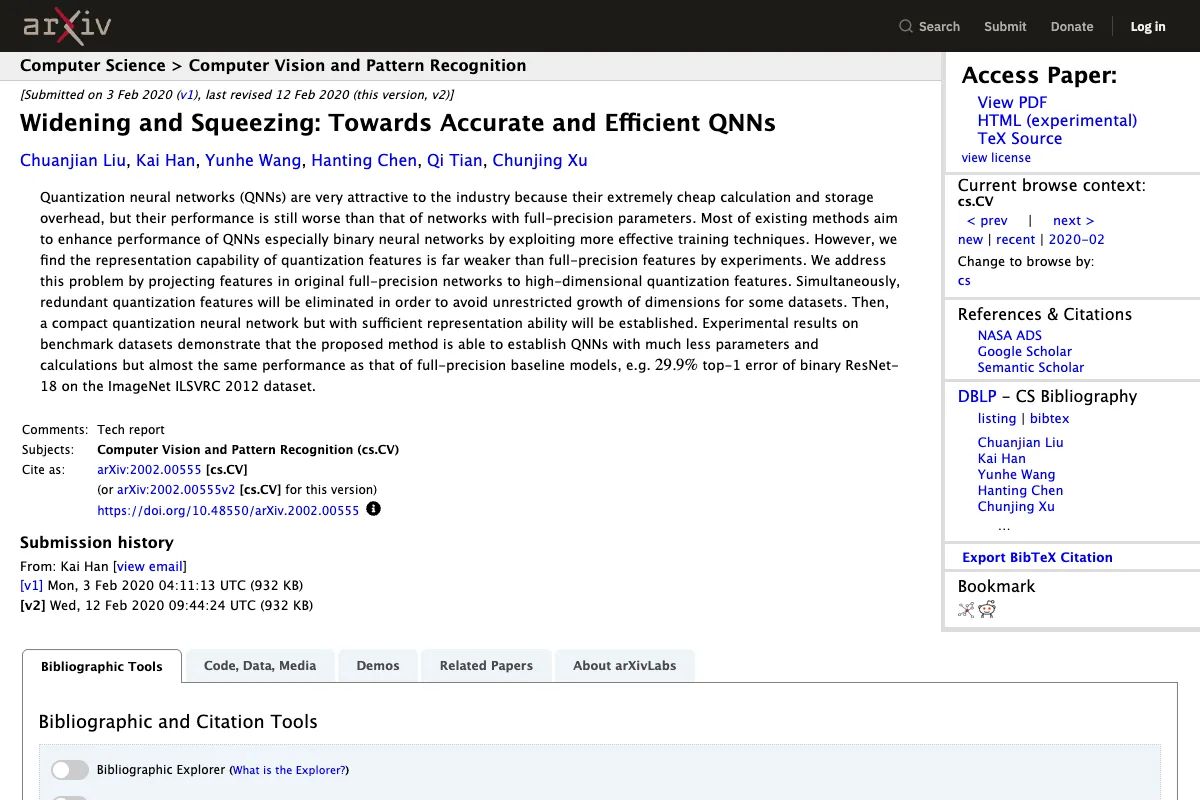
Publication: Widening and Squeezing: Towards Accurate and Efficient QNNs. Published Feb 3, 2020.
Publication: Self-Binarizing Networks. Published Feb 2, 2019.
Explore this resource at its source website for documentation and current information.
Publication: Understanding Straight-Through Estimator in Training Activation Quantized Neural Nets. Published Mar 13, 2019.
Publication: Training Quantized Nets: A Deeper Understanding. Published Jun 7, 2017.
Publication: TernGrad: Ternary Gradients to Reduce Communication in Distributed Deep Learning. Published 2017.
Publication: Training a Binary Weight Object Detector by Knowledge Transfer for Autonomous Driving. Published Apr 17, 2018.
Publication: Learning low-precision neural networks without Straight-Through Estimator(STE). Published Mar 4, 2019.
Publication: Deep Learning with Low Precision by Half-wave Gaussian Quantization. Published Feb 3, 2017.
Publication: Least squares binary quantization of neural networks. Published Jan 9, 2020.
Publication: Towards Accurate Binary Convolutional Neural Network. Published Nov 30, 2017.
Publication: Network Pruning via Transformable Architecture Search. Published May 23, 2019.
Publication: Comprehensive SNN Compression Using ADMM Optimization and Activity Regularization. Published Nov 3, 2019.
Publication: Leveraging Filter Correlations for Deep Model Compression. Published Nov 26, 2018.
Publication: Convolutional Networks for Fast, Energy-Efficient Neuromorphic Computing. Published Mar 28, 2016.
Publication: Ternary MobileNets via Per-Layer Hybrid Filter Banks. Published Nov 4, 2019.
Explore this resource at its source website for documentation and current information.
Publication: SQuantizer: Simultaneous Learning for Both Sparse and Low-precision Neural Networks. Published Dec 20, 2018.
This paper presents a pruning method, Reconstruction Error Aware Pruning (REAP), to reduce the redundancy of convolutional neural network models for accelerating the inference.…
Band-limited Training and Inference for Convolutional Neural NetworksAdam Dziedzic, John Paparrizos, Sanjay Krishnan, Aaron Elmore, Micha...
Publication: EPNAS: Efficient Progressive Neural Architecture Search. Published Jul 7, 2019.
In this work we present a method to improve the pruning step of the current state-of-the-art methodology to compress neural networks. The novelty of…
Publication: Effective Training of Convolutional Neural Networks with Low-bitwidth Weights and Activations. Published Aug 10, 2019.